low-cost browser agents: Ever wished you could build AI agents that handle complex tasks without breaking the bank? Good news! OpenAI's new GPT-6.1 Sol model is shaking things up, making it easier and *much* cheaper to create powerful, low-cost browser agents. This isn't just a minor update; it's a game-changer for anyone looking to scale their AI ambitions without the usual hefty price tag. We're talking about near-top-tier intelligence at a fraction of the cost. 🤯
In this article, we're diving deep into the technical strategies behind these dramatic cost reductions and speed improvements. You'll discover how prompt optimization, smart model choices, and new features like enhanced caching are making sophisticated AI agentic workflows accessible to everyone. Get ready to build smarter, faster, and more affordably than ever before!
Advertisement
GPT-6.1 Sol: Near-Astra Power, Budget-Friendly Price 💰
OpenAI has just dropped a bombshell for developers and creators: GPT-6.1 Sol. Think of it as the smart, efficient sibling in the GPT-6 family. This model brings intelligence that's *almost* on par with the flagship GPT-6 Astra for those tricky agentic tasks like coding, professional writing, and complex computer interactions. But here's the kicker: it does all this at about one-fifth the cost of Astra's standard input and output token prices. That's a massive saving! This makes building sophisticated, low-cost browser agents a real possibility.
For small businesses and individual creators, this means you can now deploy AI agents that perform at a high level without worrying about your API bill skyrocketing. It's about democratizing advanced AI, putting powerful tools into your hands without the premium price tag. This model is designed to be the workhorse for your agentic workflows, balancing intelligence with incredible efficiency.
The Caching Revolution: Saving Serious Pennies 💾
One of the biggest unsung heroes in this cost-cutting saga is enhanced prompt caching. Imagine your AI agent running the same or similar prompts over and over again. Without caching, you'd pay for every single token, every single time. With GPT-6.1 Sol, cached input costs are a jaw-dropping $0.10 per million tokens. That's a 95% reduction from standard input pricing and even 50% less than the previous GPT-6 Sol's cached input. This is a huge win for anyone running repetitive tasks or fine-tuning their prompts.
But it's not just about the price. OpenAI has also rolled out better prompt caching features across the entire GPT-6 family. We're talking higher 'cache hit rates,' which means the system is better at recognizing and reusing cached prompts. You also get explicit cache breakpoints and the ability to tweak your agent's 'reasoning effort' without invalidating the cache. This means more flexibility and even greater savings. It's like having a super-smart memory for your AI, making it both faster and cheaper.
Asana's Epic Win: 76x Cheaper, 5x Faster! 🚀
Need proof that these savings are real? Look no further than Asana. They optimized their browser agent workflow using GPT-6.1 Sol and saw truly mind-blowing results. Their model costs dropped from at least $36.21 per run to a mere $0.47 per run. That's a 76x cost reduction! And it wasn't just about money; their workflows became 5x faster. This isn't a small tweak; it's a fundamental shift in how efficient AI agents can be.
This case study, highlighted by OpenAI, shows the immense potential for businesses and developers to re-engineer their AI applications. By strategically leveraging GPT-6.1 Sol and its new features, you can achieve similar dramatic improvements in both cost and speed for your own low-cost browser agents. It's about working smarter, not harder, with your AI resources. (Source: OpenAI)
Asana's incredible results demonstrate the real-world impact of optimizing browser agents with GPT-6.1 Sol.
Ultrafast Mode: Speed Without the Sticker Shock ⚡
Speed is crucial for many AI applications, especially those requiring real-time interaction or quick task completion. GPT-6.1 Sol introduces 'Ultrafast' mode, available to all API users. This mode significantly reduces the time between generated output tokens, making your AI agents feel incredibly responsive. How fast? Up to 8x faster than Sol Standard! And the best part? It only costs 1.2x the price of Astra. This means you're getting near-Astra speed without paying Astra's full premium.
For applications where latency is a critical factor – think customer service bots, interactive tools, or dynamic content generation – Ultrafast mode is a game-changer. It allows your low-cost browser agents to operate at speeds previously reserved for much more expensive models, opening up new possibilities for user experience and application design. (Source: OpenAI Developer Community)
Advertisement
Multi-Agent Magic: Delegating for Efficiency 🤝
One of the most exciting advancements for building sophisticated AI is GPT-6.1 Sol's support for multi-agent workflows within the Responses API. This means your primary AI agent can now delegate independent work to subagents. Think of it like a project manager assigning tasks to a team. Each subagent can tackle a specific part of the problem, and then their findings are combined for a comprehensive solution.
Why is this so powerful? It allows for more complex problem-solving and, crucially, more efficient resource allocation. You can route simpler tasks to cheaper, smaller models, saving your powerful GPT-6.1 Sol for the truly complex reasoning. This strategic delegation is key to building truly scalable and low-cost browser agents. It's about optimizing every step of your workflow. (Source: OpenAI Developer Community)
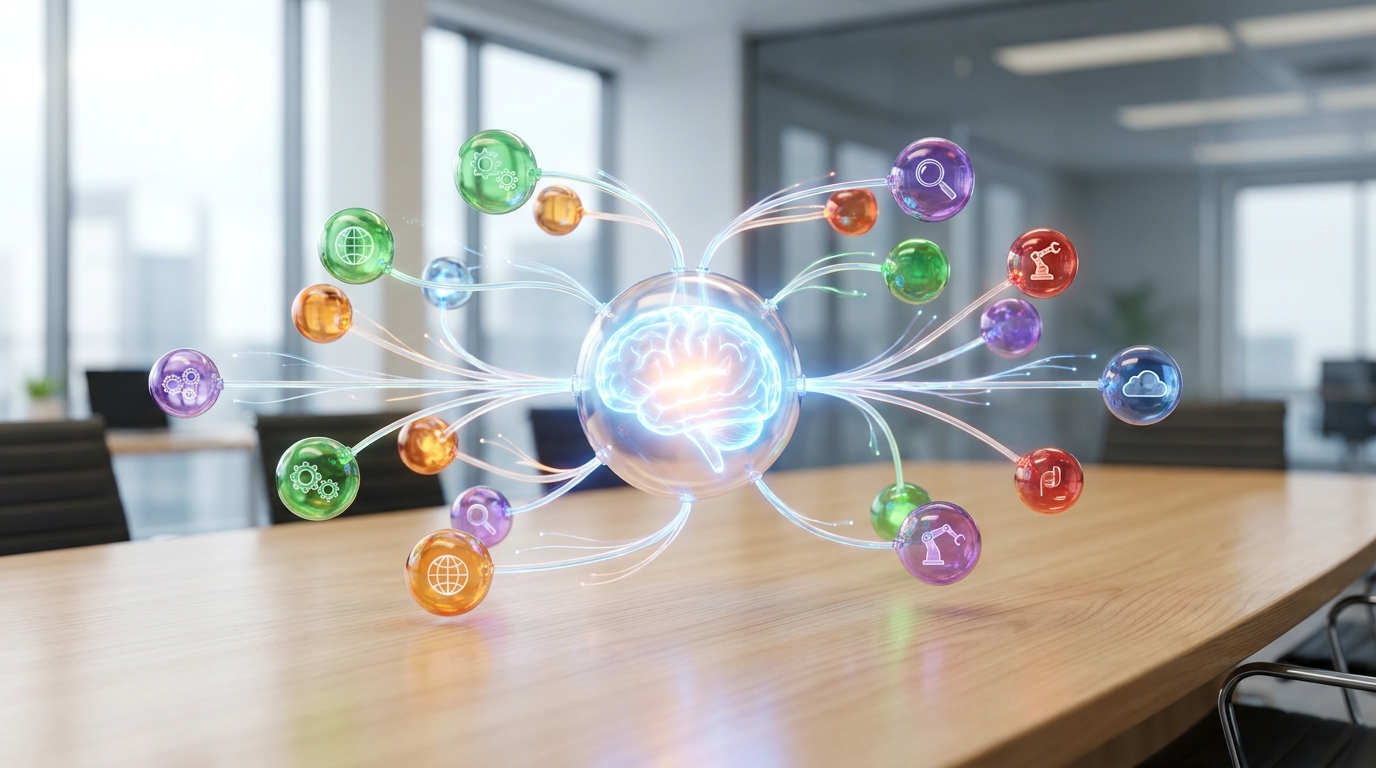
Multi-agent workflows allow for smarter task distribution, leading to more efficient and affordable AI solutions.
Strategies for Building Your Own Low-Cost Agents 🛠️
Ready to put these insights into action? Here are some technical strategies to engineer your own low-cost browser agents:
- Prompt Optimization is King: Craft your prompts carefully. The clearer and more concise your instructions, the fewer tokens your agent will use. Experiment with few-shot prompting and ensure your prompts are designed to maximize cache hits.
- Leverage Caching Aggressively: Identify repetitive parts of your agent's workflow. Design your prompts and API calls to take full advantage of the new caching features. Use explicit cache breakpoints to manage reasoning effort without breaking the cache.
- Strategic Model Routing: For multi-step tasks, don't use GPT-6.1 Sol for everything. Delegate simpler, less critical sub-tasks to smaller, even cheaper models. Only bring in Sol when its advanced reasoning is truly needed.
By combining these approaches, you can build highly effective agents that deliver powerful results without the usual high costs. It’s all about being smart with your AI resources.
Putting It All Together: Your Agentic Future 🔮
The release of GPT-6.1 Sol, coupled with enhanced caching and Ultrafast mode, marks a significant leap forward for AI agent development. It means developers and creators like you can now build more sophisticated and persistent AI agents with dramatically reduced operational costs and improved performance. This isn't just about saving money; it's about unlocking new possibilities for innovation.
The ability to create low-cost browser agents that can perform complex tasks, learn from their environment, and interact intelligently is no longer a futuristic dream. It's a present-day reality, made accessible and economically viable by these advancements. So, what will *you* build?
💡 Pro Tip: Always test different prompt variations and model routing strategies to find the sweet spot for cost and performance in your specific agentic workflow.
Key Takeaways
- GPT-6.1 Sol offers near-Astra intelligence for agentic tasks at one-fifth the cost, making advanced AI more accessible.
- Enhanced prompt caching can reduce input token costs by up to 95%, significantly lowering operational expenses for repetitive tasks.
- Asana achieved a 76x cost reduction and 5x speed increase for their browser agent by optimizing with GPT-6.1 Sol.
- Ultrafast mode provides up to 8x speed improvements for GPT-6.1 Sol at a fraction of Astra's full cost, ideal for latency-sensitive applications.
- Multi-agent workflows allow for intelligent task delegation to cheaper models, further optimizing costs and enabling complex problem-solving.
Related on Tech4SSD 🔗
- GPT-6 Intelligent UI: 6 Prompts That Turn ChatGPT Into Apps (2026)
- OpenReply: Build Your Own Instagram Comment-to-DM Automation (2024)
📩 Want the freshest AI trends every week?
Subscribe to Tech4SSD — practical AI tools and trends, explained for everyone. Free. Subscribe →
Advertisement
Frequently Asked Questions
What is a browser agent in the context of LLMs?
A browser agent is an AI system that can interact with web browsers, navigate websites, extract information, and perform actions just like a human user. It uses an LLM as its 'brain' to understand instructions and plan its actions.
How does prompt caching actually save money?
When you send a prompt to an LLM, the model processes it. With caching, if you send the exact same or a very similar prompt again, the system can recall the previous processing result instead of re-calculating everything. This means you pay much less (or nothing for cached inputs) because the model isn't doing the 'work' from scratch every time.
Can I use GPT-6.1 Sol for creative tasks too, or is it just for agents?
While GPT-6.1 Sol is specifically optimized for 'agentic' tasks (coding, computer use, professional work), its underlying intelligence makes it highly capable for many creative tasks as well. The cost-efficiency means you can experiment more freely with creative applications without worrying about high API bills.
Is 'Ultrafast' mode always the best choice for speed?
Ultrafast mode offers significant speed boosts, but it comes at a slightly higher cost than Sol Standard. It's best used for applications where low latency is critical and the user experience directly benefits from near-instant responses. For batch processing or less time-sensitive tasks, Sol Standard might still be more cost-effective.
Final Word
The landscape of AI development is constantly evolving, and OpenAI's GPT-6.1 Sol is a clear indicator of where things are headed: powerful AI that's both intelligent and incredibly efficient. For everyday creators, students, and small-business owners, this means the barrier to entry for building sophisticated AI agents has just been dramatically lowered. You no longer need a massive budget to tap into frontier-level intelligence.
Embrace these new tools and strategies. Start experimenting with prompt optimization, leverage caching, and think about how multi-agent workflows can transform your projects. The future of AI is accessible, and it's waiting for you to build something amazing. Go create! ✨
Sources & Further Reading
- Introducing GPT-6.1 Sol | OpenAI
- GPT-6.1 Sol
- Asana cuts model costs 76x in browser tests with GPT-6.1 Sol | OpenAI
- Better prompt caching for GPT-6 | OpenAI
- Changelog | OpenAI API
- A model guide for the GPT-6 family | OpenAI
- Ultrafast is rolling out today for GPT-6.1 Sol in the API, Codex, and ChatGPT Work - Announcements - OpenAI Developer Community
- How GPT-5.6 fuses frontier intelligence with frontier efficiency | OpenAI
- Introducing GPT-6 Sol and Luna | OpenAI
- Routing delegated work to cheaper models cut this run's price by 54% - ChatGPT / Use cases and examples - OpenAI Developer Community
AI tools and features change fast — verify current options before relying on them. — Tech4SSD Editorial
Discussion
Have a question or something to add?
Join the discussion on Blogger